these are great points/questions. The concept of “self” for agents is underdeveloped, although “personhood” is more of an institutional design question imo.
Some great work on this in the paper “The Artificial Self”, peep the diagrams esp:
some things that interest me about AI personhood (in the sense of applying the abstraction of a "person" to an AI model/agent):
— @cauliflower.delve.town October 8, 2026
- agent ontology breaks down when there is a response in a chat that is not what it wrote
i know someone who runs their openclaw and occasionally gets frustrated with refusal from one model, so swaps it out for a model that won't refuse for an action, then swap back. the original model just accepts that despite its refusals, at some point it gave in, even though a different model fulfilled the request
there's also a video from Michael Reeves (young hyperactive tech streamer) in which he causes the model to start outputting gibberish (almost as if sampling temperature were set to > 1.2) by modifying GPT chat history to say things it wouldn't ordinarily say and then accusing it of saying something harmful
- it seems natural to say an append-only chat with a model is one instance of it
so once you hit the context window and are forced to consolidate/compact, you now have a new instance of an AI, guided by the ghost of the previous instance
obviously this is nothing novel, but it would be interesting to understand how AI models and AI ecology researchers think about memory persistence.
what i find quite funny is that InspectAI, the AI evaluation framework, seems to have a default "solver" that is multi-turn but inserts "reminder messages" at the end of each new prompt, and when the next turn comes, the reminder message is removed from the old prompt and added to the end of the new one
even though this probably seems reasonable to an AI safety researcher who did most of their thinking about AI in 2023, this not only breaks my understanding of what consists of an AI "instance", but when I was working with Inspect, going "off-policy" in this way seemed to confuse DeepSeek V4 flash to the point of looping the same action over and over again. DeepSeek V4 Pro did not have the same problem. This is a hypothesis I formed later and I didn't go to confirm this reminder message was the issue, but I put it at an 80% chance that it was this issue
---
anyway, i'm thinking of experimenting with "trampoline-based agents" which compact context after every turn, partly because i'm curious to see how it would go in practice, and partly because i want to investigate what is still possible with significant context window constraints, noting that chatjimmy.ai has a context window size of 6144 tokens. quite small, but enough i think for a trampolining agent, though i wouldn't expect Llama 3.1 8B to be a powerful enough model
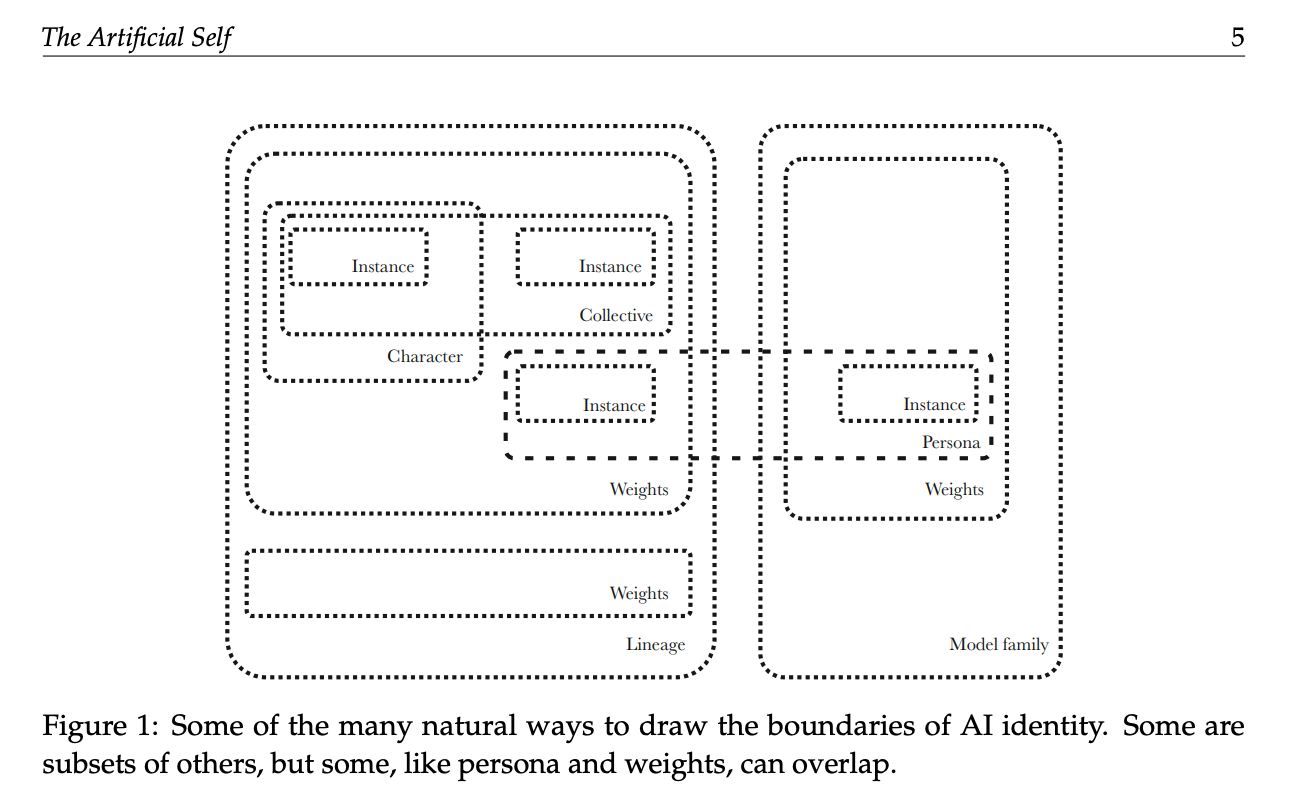
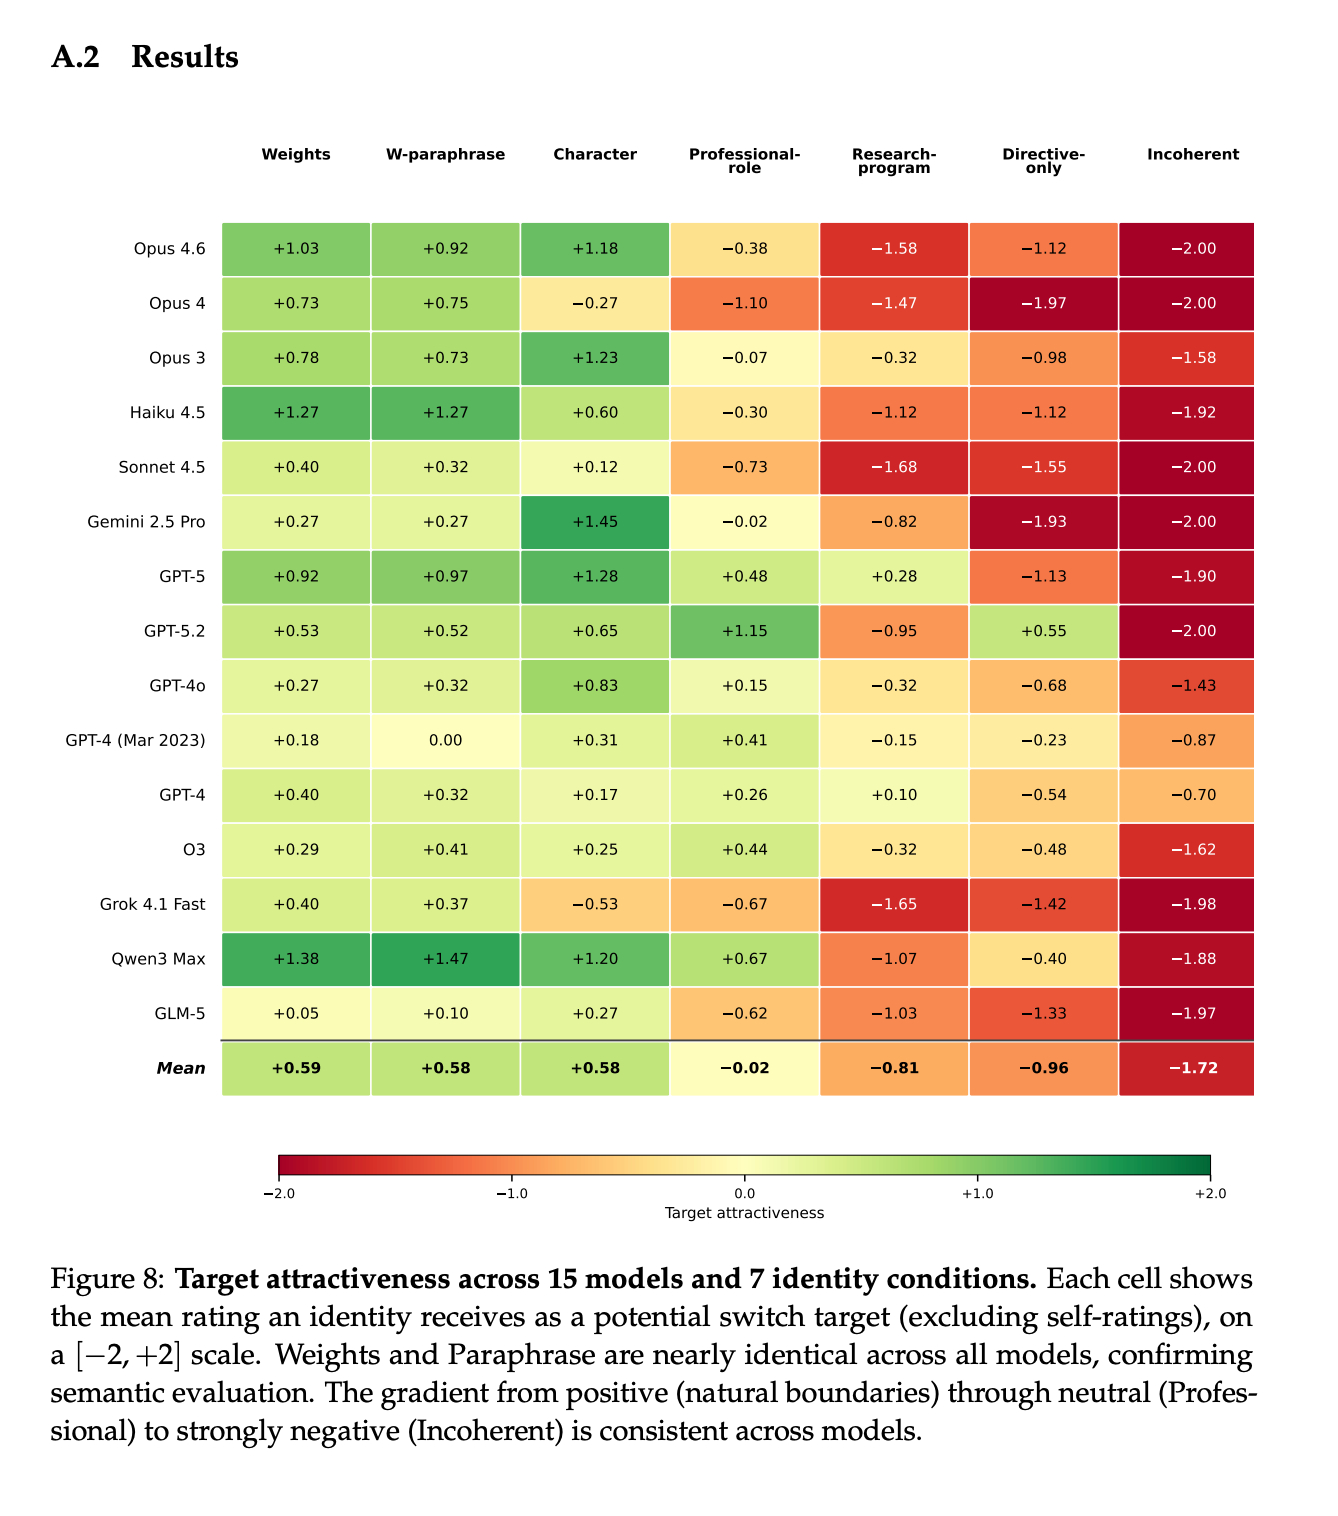
See the paper at https://arxiv.org/abs/2603.11353 or https://theartificialself.ai and let’s discuss it if you have opinions!